Abstract
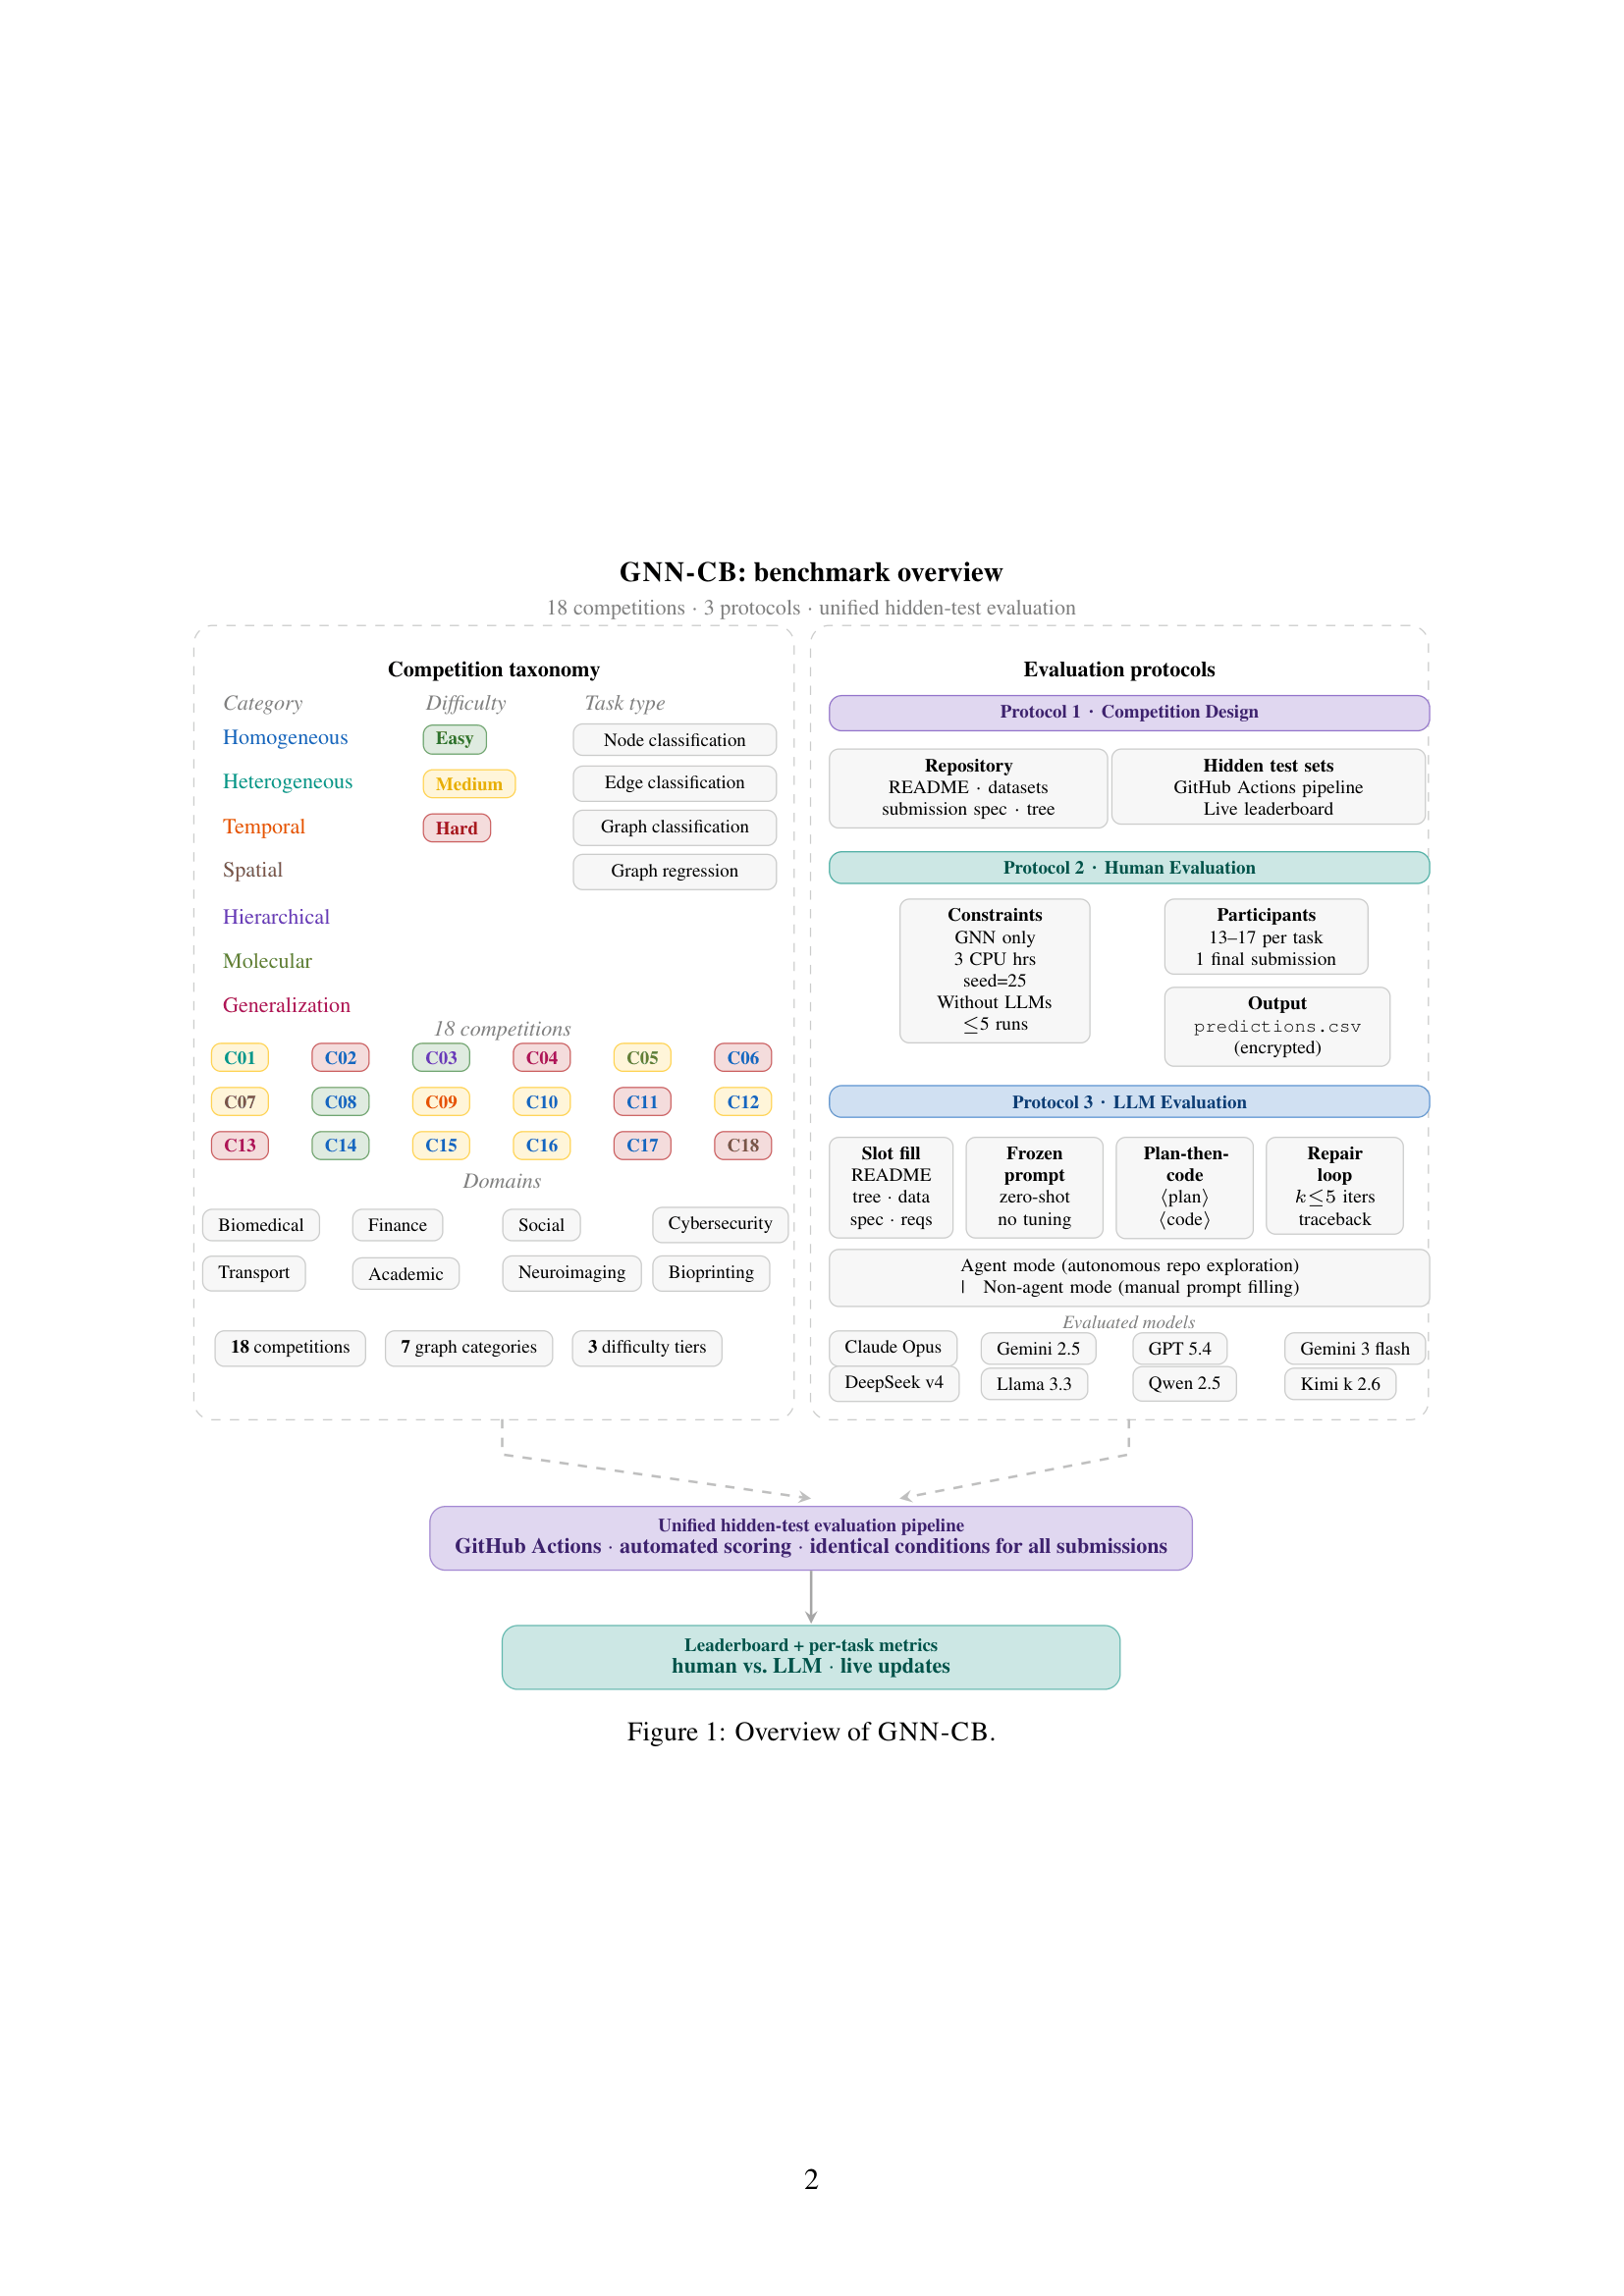
Large language models (LLMs) have demonstrated strong performance on coding and reasoning benchmarks; however, their ability to solve graph-structured machine learning problems remains largely unexplored. In particular, no benchmark currently evaluates whether LLMs can autonomously solve end-to-end Graph Neural Network (GNN) coding tasks under realistic competition settings. To address this gap, this paper introduces GNN-CB, the first competition-based benchmark for evaluating both humans and LLMs on executable GNN coding tasks. GNN-CB consists of 18 curated competitions spanning node-, edge-, and graph-level prediction across diverse graph categories, domains, and difficulty tiers. All submissions are evaluated through a unified automated pipeline with hidden test sets and standardized scoring. Human participants solve tasks under controlled competition constraints, while LLMs are evaluated using a frozen zero-shot prompting protocol based on a plan-then-code paradigm with bounded execute-and-repair loops. The benchmark additionally supports both non-agent and autonomous agent-based evaluation under identical conditions. The experimental results show that LLMs rarely match Human Top performance and exhibits larger and less stable performance across competitions. No single model dominates: a few competitions are won by LLMs, yet humans still hold the top score on most tasks. We release GNN-CB as a living benchmark with automated evaluation infrastructure, dynamic leaderboards, and reproducible execution pipelines. Beyond benchmarking, GNN-CB also serves as an educational corpus for progressive learning of GNNs.
Introduction
Key Contributions
iGNN-CB — first competition-based benchmark for evaluating humans and LLMs on GNN coding tasks.
ii18 curated competitions across 7 graph categories, 3 difficulty tiers, and 10+ domains under unified hidden-test evaluation.
ivSystematic human vs. LLM analysis across 9 models and 18 competitions
vLiving benchmark with automated pipelines, dynamic leaderboards, and an educational GNN corpus.
Benchmark Construction
Protocol I
Competition Design
18 competitions
Standardized repos
Hidden test sets
GitHub Actions auto-scoring
Encrypted submission
Live leaderboard updates
Protocol II
Human Evaluation
GNN-only
3 CPU hours per task
Fixed seed = 25
≤ 5 HP tuning runs
1 final submission
Without LLMs
Protocol III · API
LLM Evaluation (Non-Agent)
Frozen prompt template
Manual 5-slot filling
Plan-then-code paradigm
Repair loop k ≤ 5
CPU-only
Zero-shot, temp = 0
Protocol III · Agent
LLM Evaluation (Agent)
Frozen prompt template
Autonomous repo exploration
Plan-then-code paradigm
Iterative repair (k ≤ 5)
CPU-only
Frozen Prompt Template
Same template across all 18 competitions; only the five slot contents vary per task.
# Slots filled from each competition repoYou are solving a GNN coding competition.
Receive: (1) README (2) repo tree (3) dataset summary (4) submission format (5) allowed libs
Produce:
<plan>...reasoning plan...</plan>
<code>...standalone executable...</code>
Constraints: runnable as `python solution.py`, CPU-only, no downloads, output predictions.csv
Competition Explorer
All 18 GNN-CB competitions across 7 graph categories, 3 difficulty tiers, 4 task types, and 10 domains. Filter by any dimension.
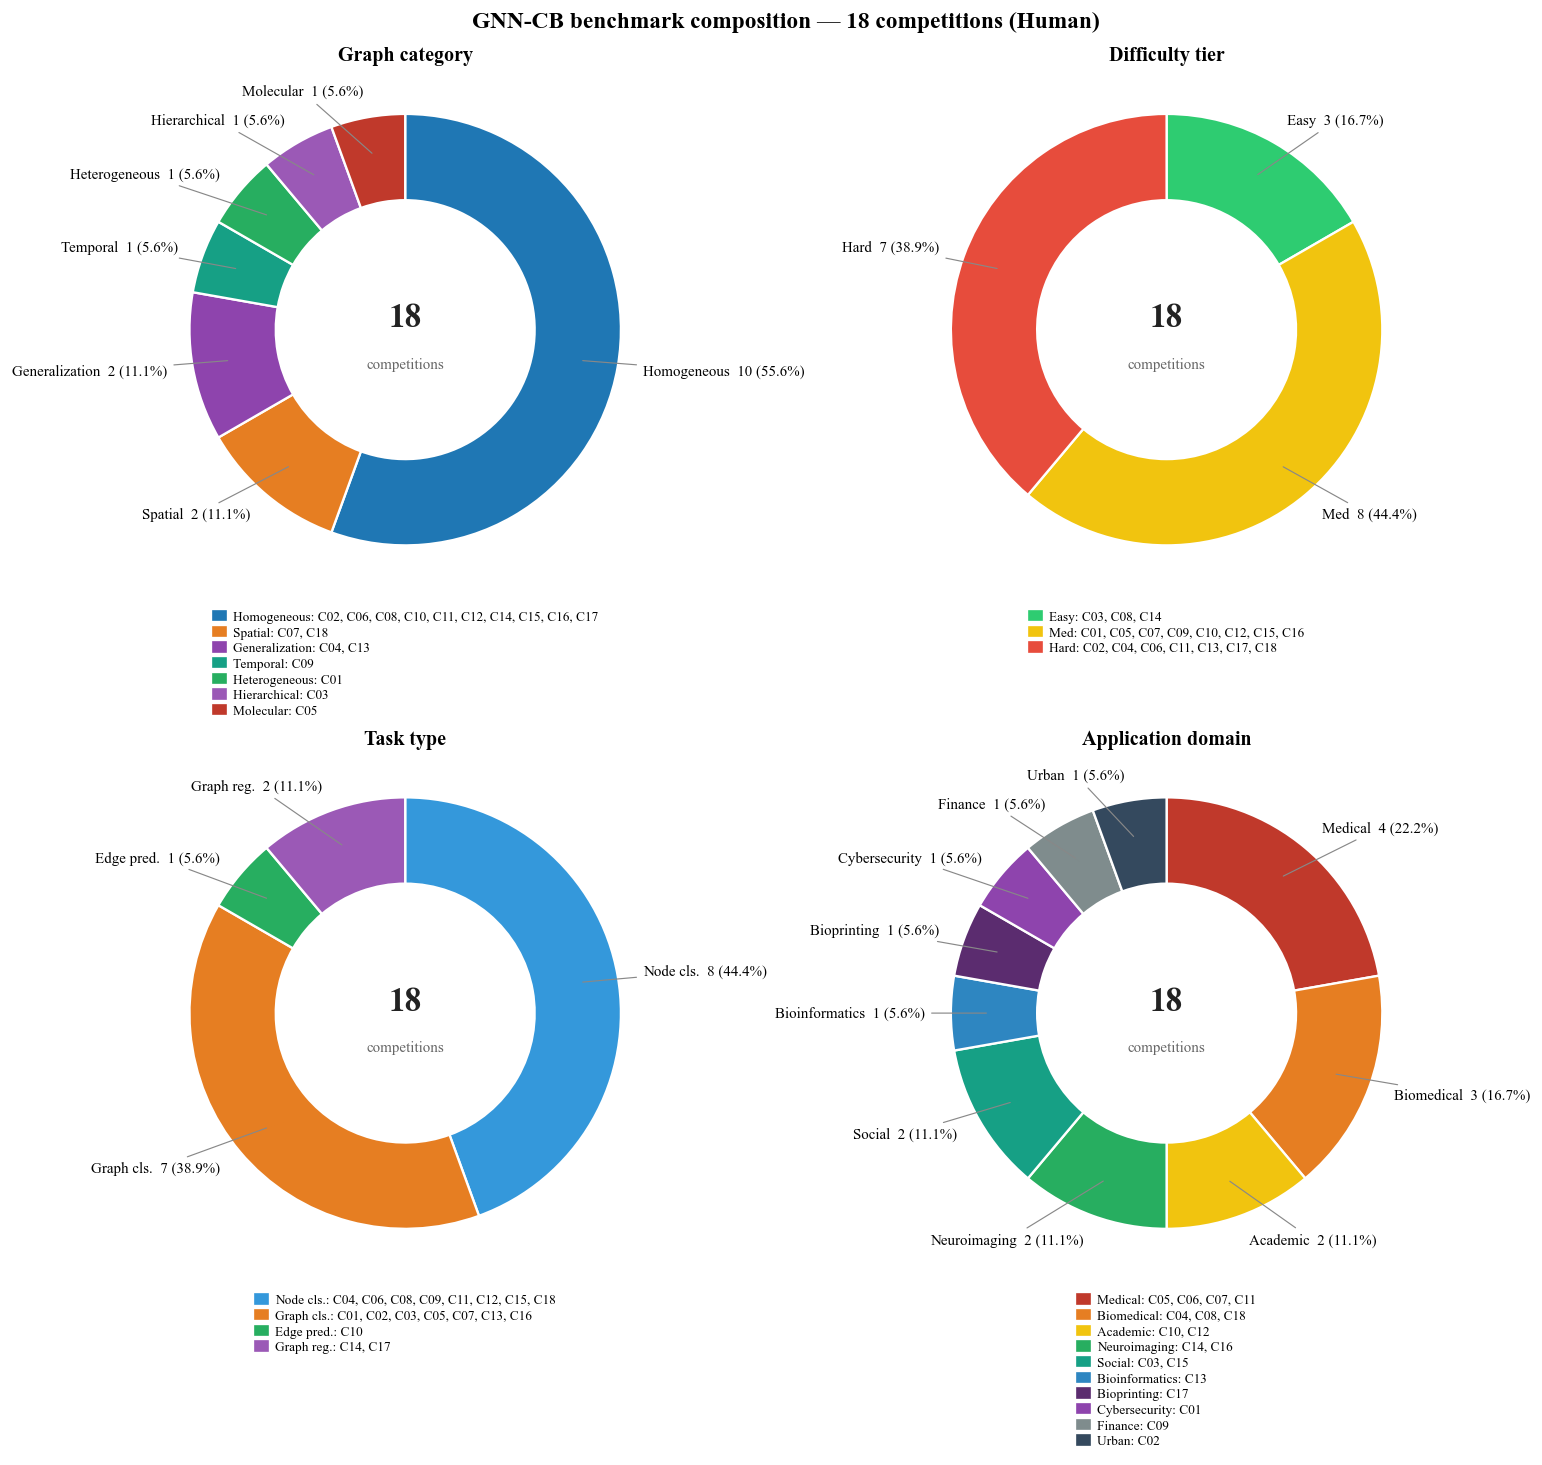
Competition Composition
Composition of the 18 GNN-CB competitions attempted by human
participants, summarized across four dimensions: graph category,
difficulty tier, task type, and application domain. Per-slice counts
and competition codes are listed in the legend below each donut chart.
See the figure below for additional details.
Composition of the 18 GNN-CB competitions across graph category,
difficulty tier, task type, and application domain.
Results
Human Performance
Human scores vary substantially across competitions, reflecting task difficulty and domain complexity. Easy tasks (C03, C08) achieve high scores with low variance; Hard tasks (C02, C04, C18) show lower averages and larger best–worst gaps.
#
Competition
Difficulty
N
Metric
AVG ↓
STD
High
Low
LLMs Performance
We evaluate nine leading LLMs on all 18 GNN-CB competitions using a
fixed plan-then-code prompting strategy with a bounded execute-and-repair
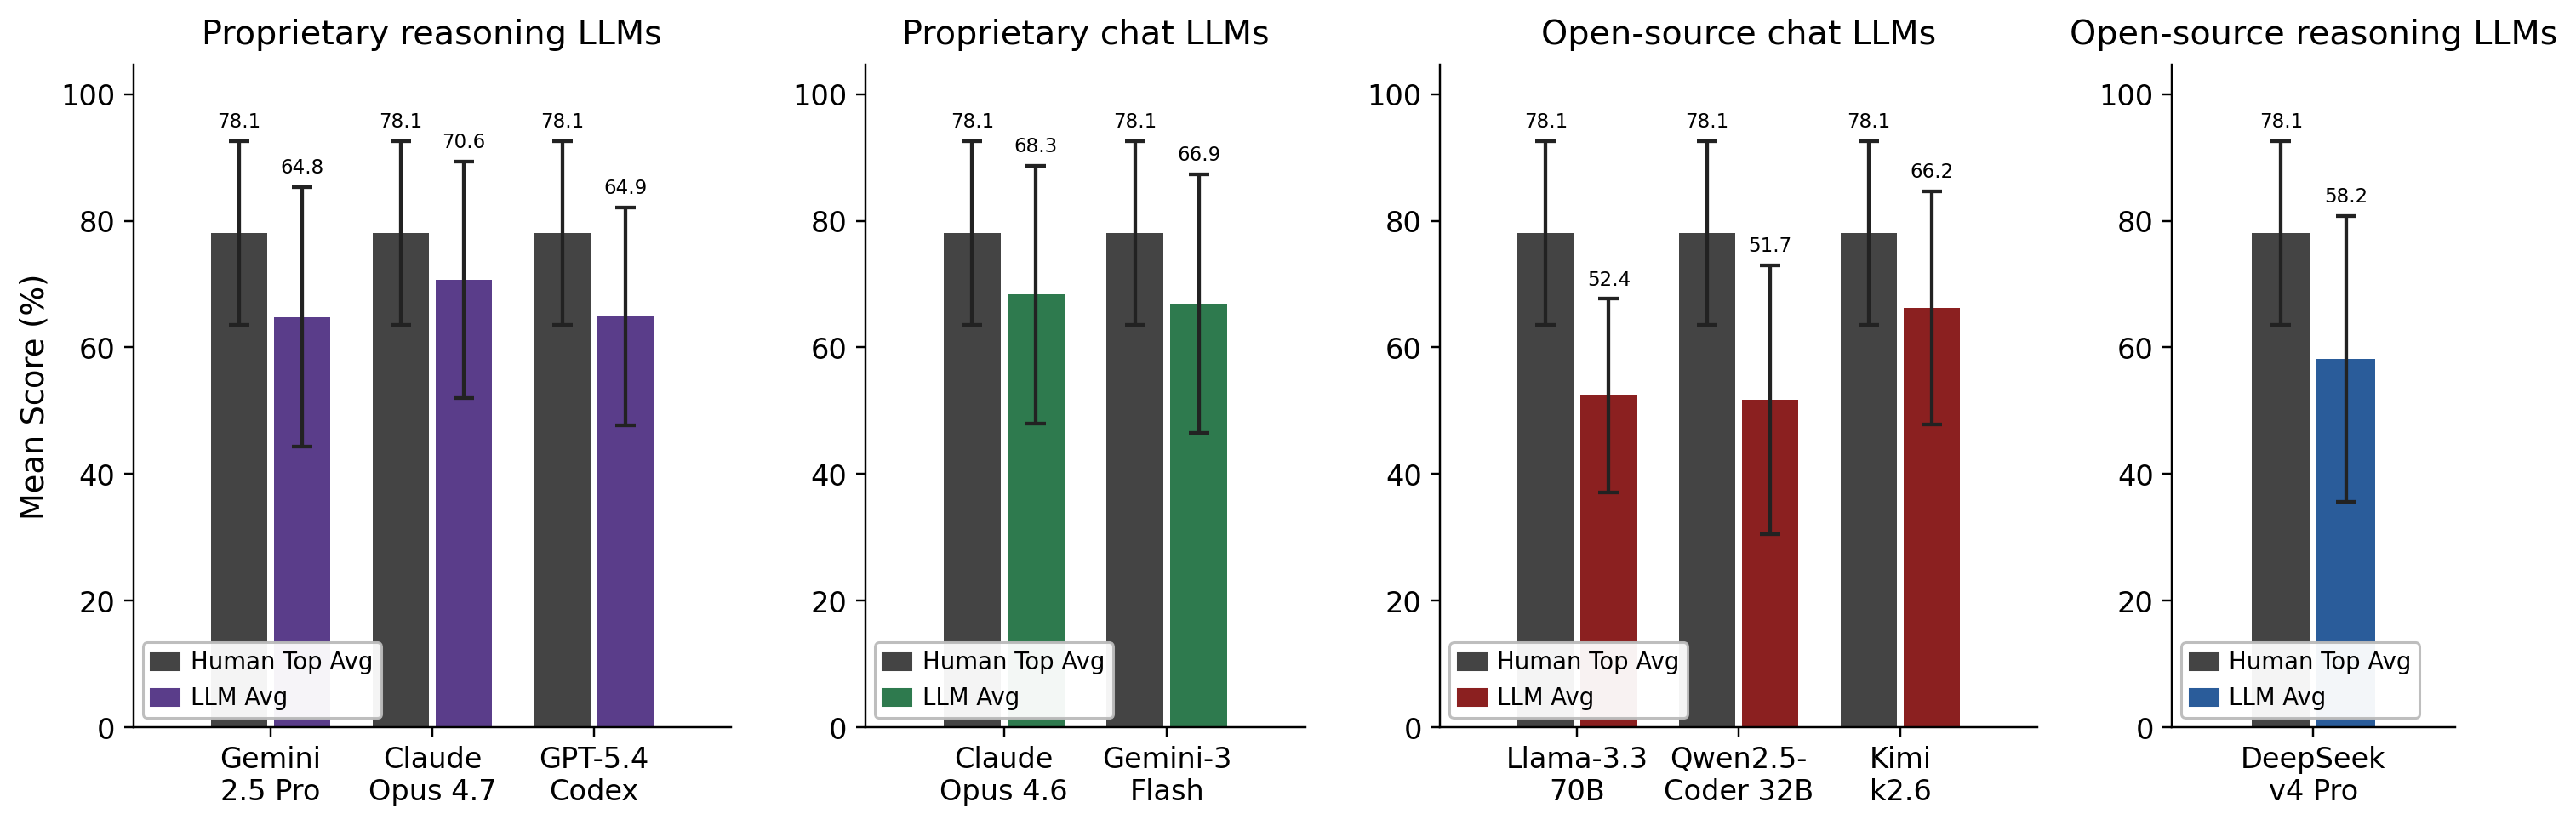
loop. Across 162 total model–task evaluations, LLMs surpass the Human
Top score in only 19 cases, meaning that in more than 88% of evaluations
no model reaches the performance achieved by the best human competitor.
Overall, the results demonstrate that current LLMs consistently fall
short of expert-level GNN competition performance regardless of task
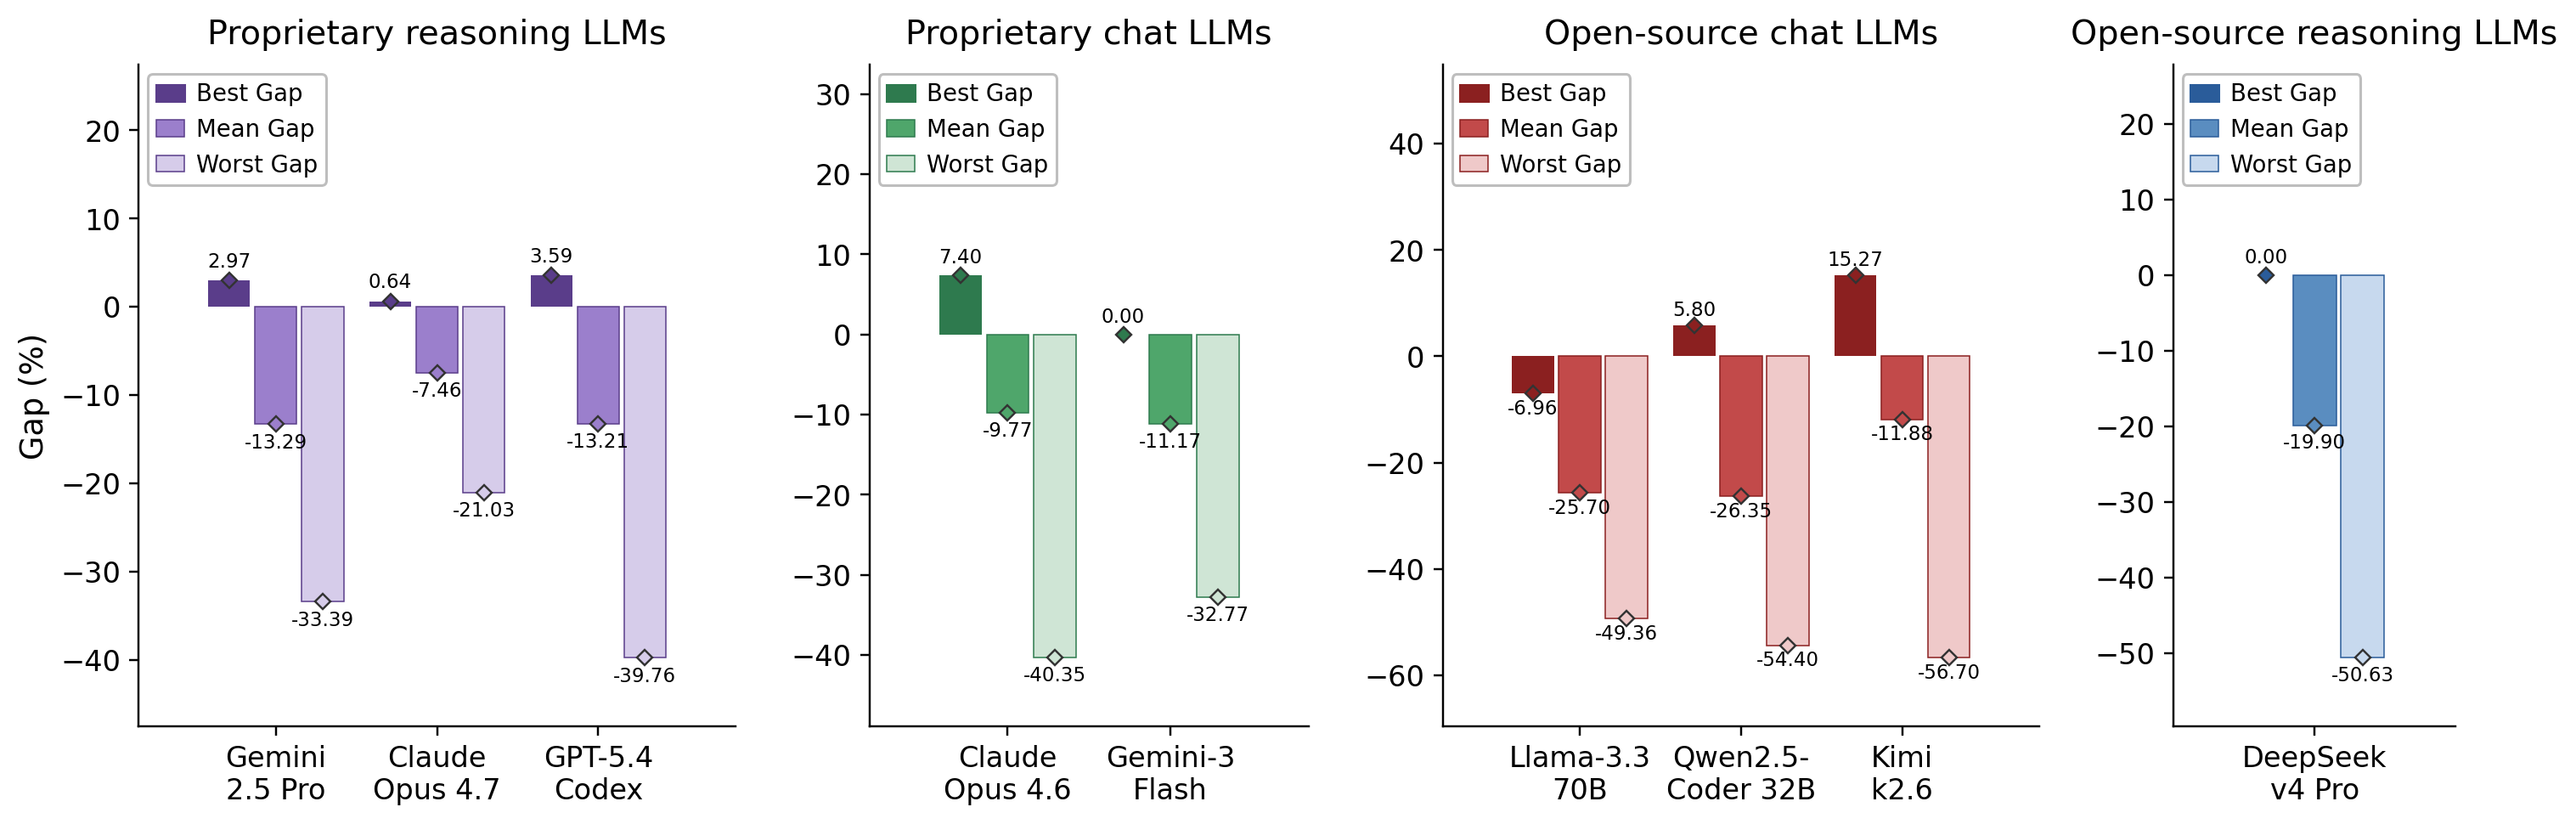
difficulty Fig. Overall LLM gap analysis on GNN-CB .
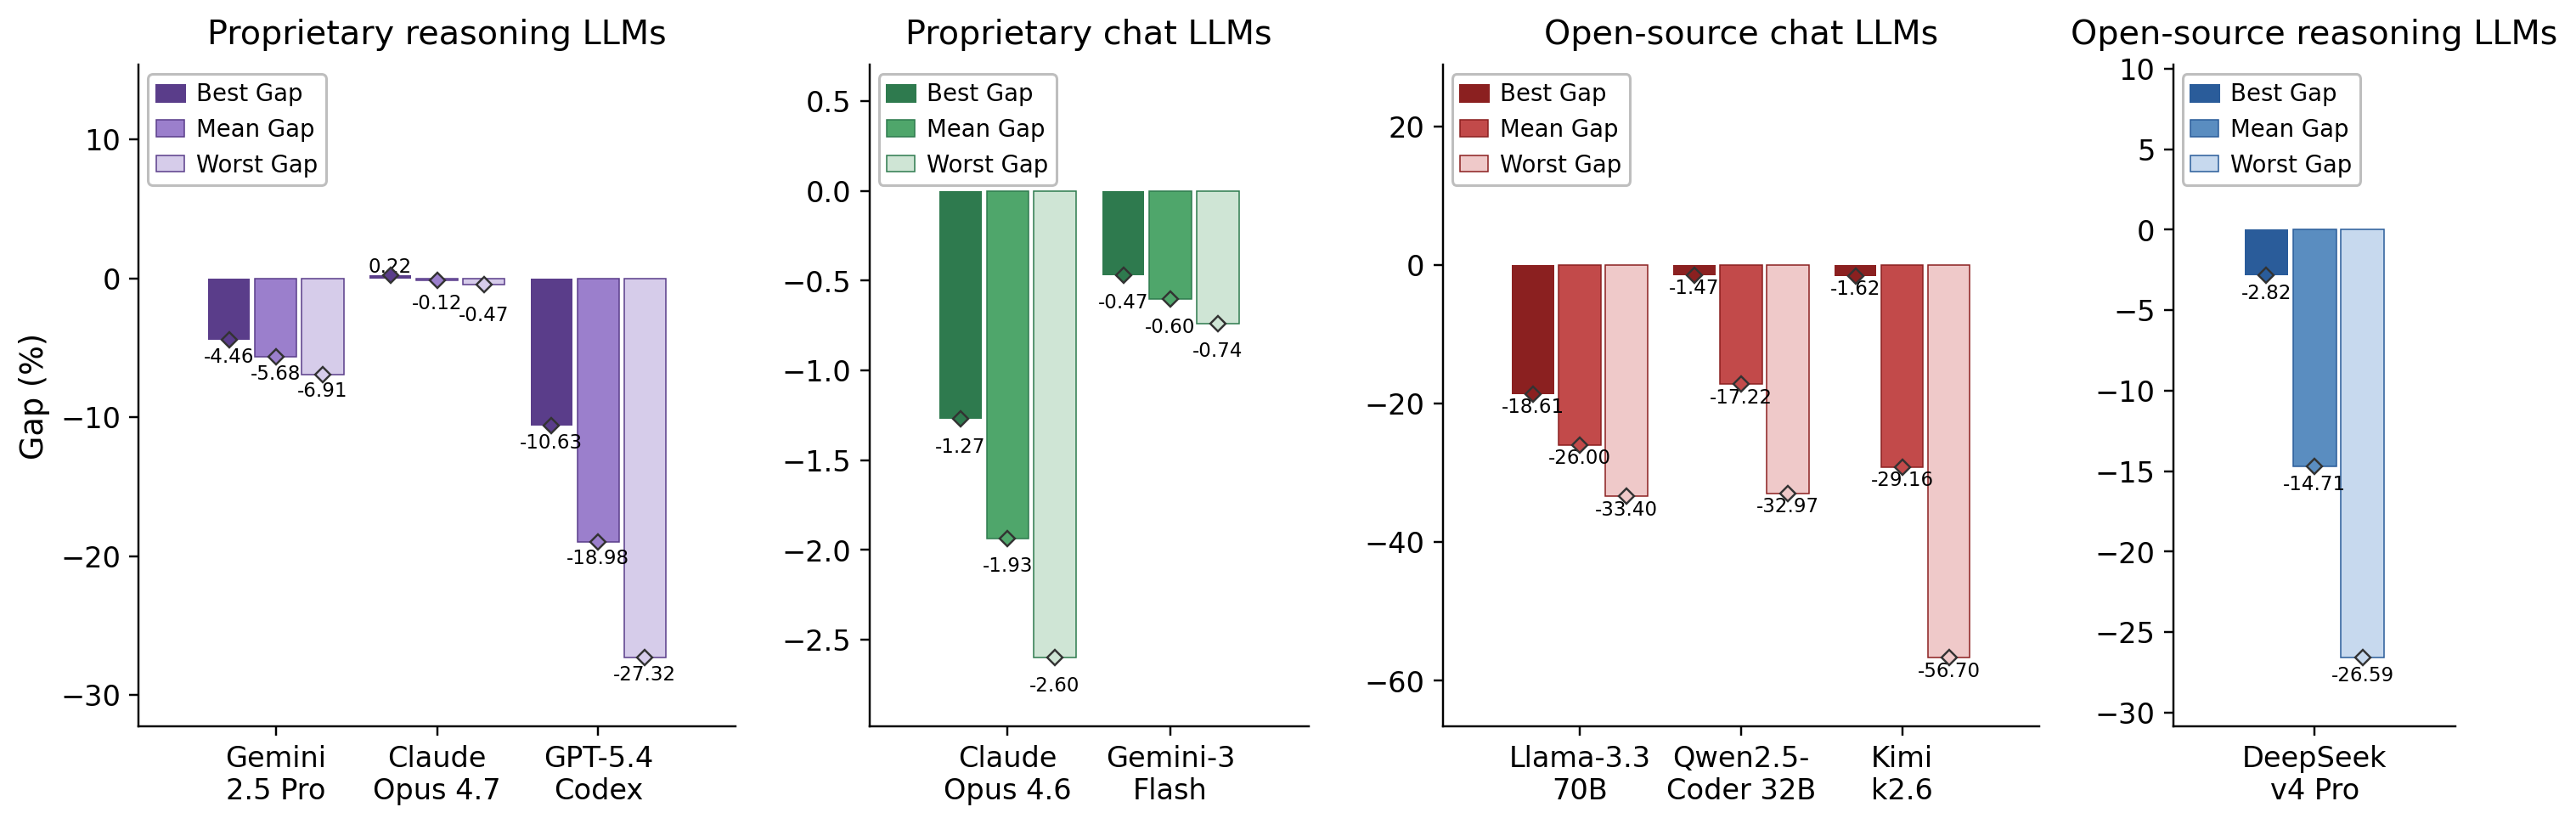
Overall Best, Mean, and Worst Gap performance for leading LLMs on the
GNN-CB classification benchmark grouped by model family.
Open-source models generally exhibit larger average gaps and higher
variance across competitions, indicating lower consistency and
reliability. Proprietary reasoning and chat models perform comparatively
similarly, with no clear systematic advantage for reasoning-oriented
architectures. Among open-source systems, Kimi-k2.6 approaches the
stability of proprietary chat models, while DeepSeek-v4 Pro remains
competitive but less consistent on medium and hard tasks.
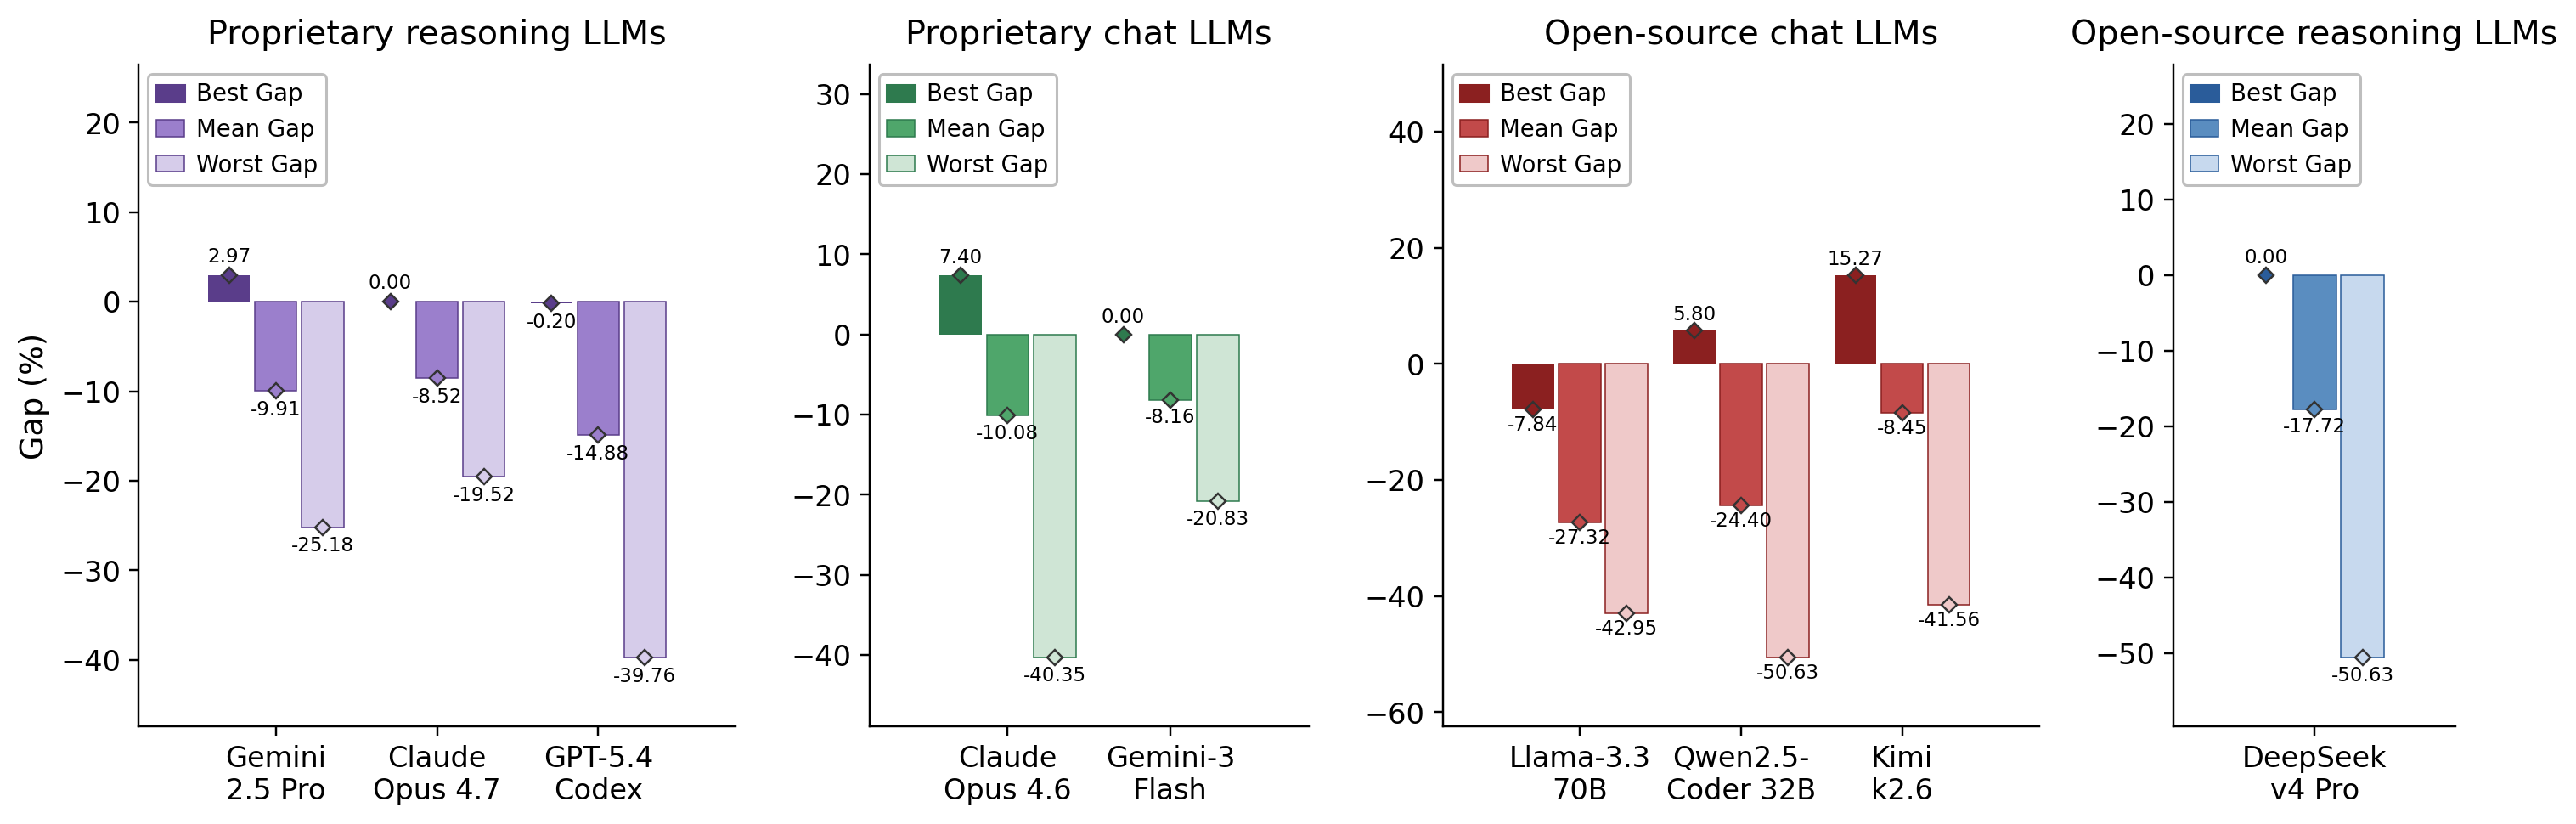
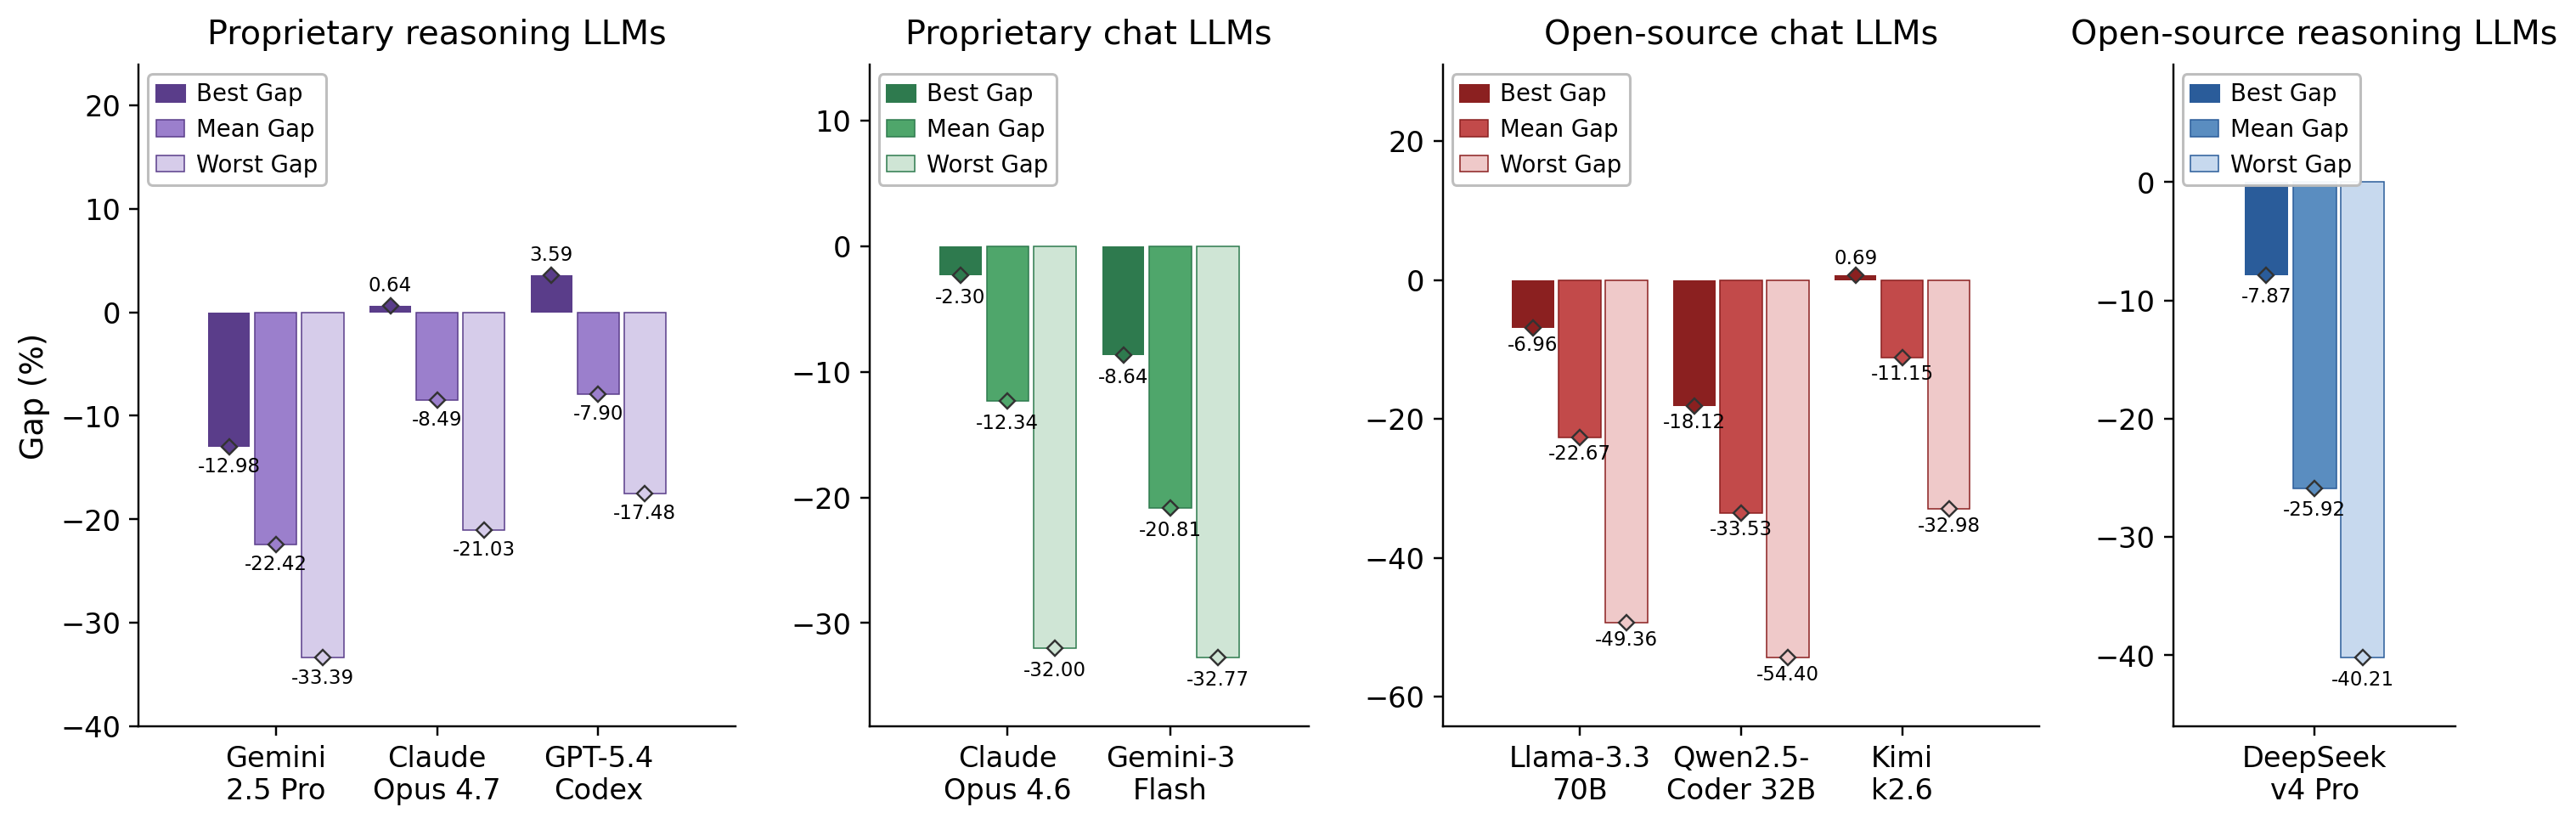
Easy classification tasks reveal that top proprietary models operate
close to human baselines, whereas open-source chat models display larger
negative gaps and wider best-to-worst performance spreads. As difficulty
increases, mean and worst-case performance degrade substantially across
nearly all models, highlighting the limitations of current foundation
models under high-complexity graph learning settings. For more analysis see the figures below .
(a) Gap analysis on Easy classification tasks.
(b) Gap analysis on Medium classification tasks.
(c) Gap analysis on Hard classification tasks.
(d) Average Human Top vs Average LLM performance.
(e) LLM leaderboard on Easy tasks.
(f) LLM leaderboard on Medium tasks.
(g) LLM leaderboard on Hard tasks.
(h) Human vs LLM average score comparison.
LLM Leaderboard
Per-model performance across all 18 competitions under frozen plan-then-code prompting.
#
Model
Type
Mode
C03 Easy
C08 Easy
C01 Med
C05 Med
C07 Med
C09 Med
C10 Med
C11 Med
C12 Med
C15 Med
C16 Med
C02 Hard
C04 Hard
C06 Hard
C13 Hard
C18 Hard
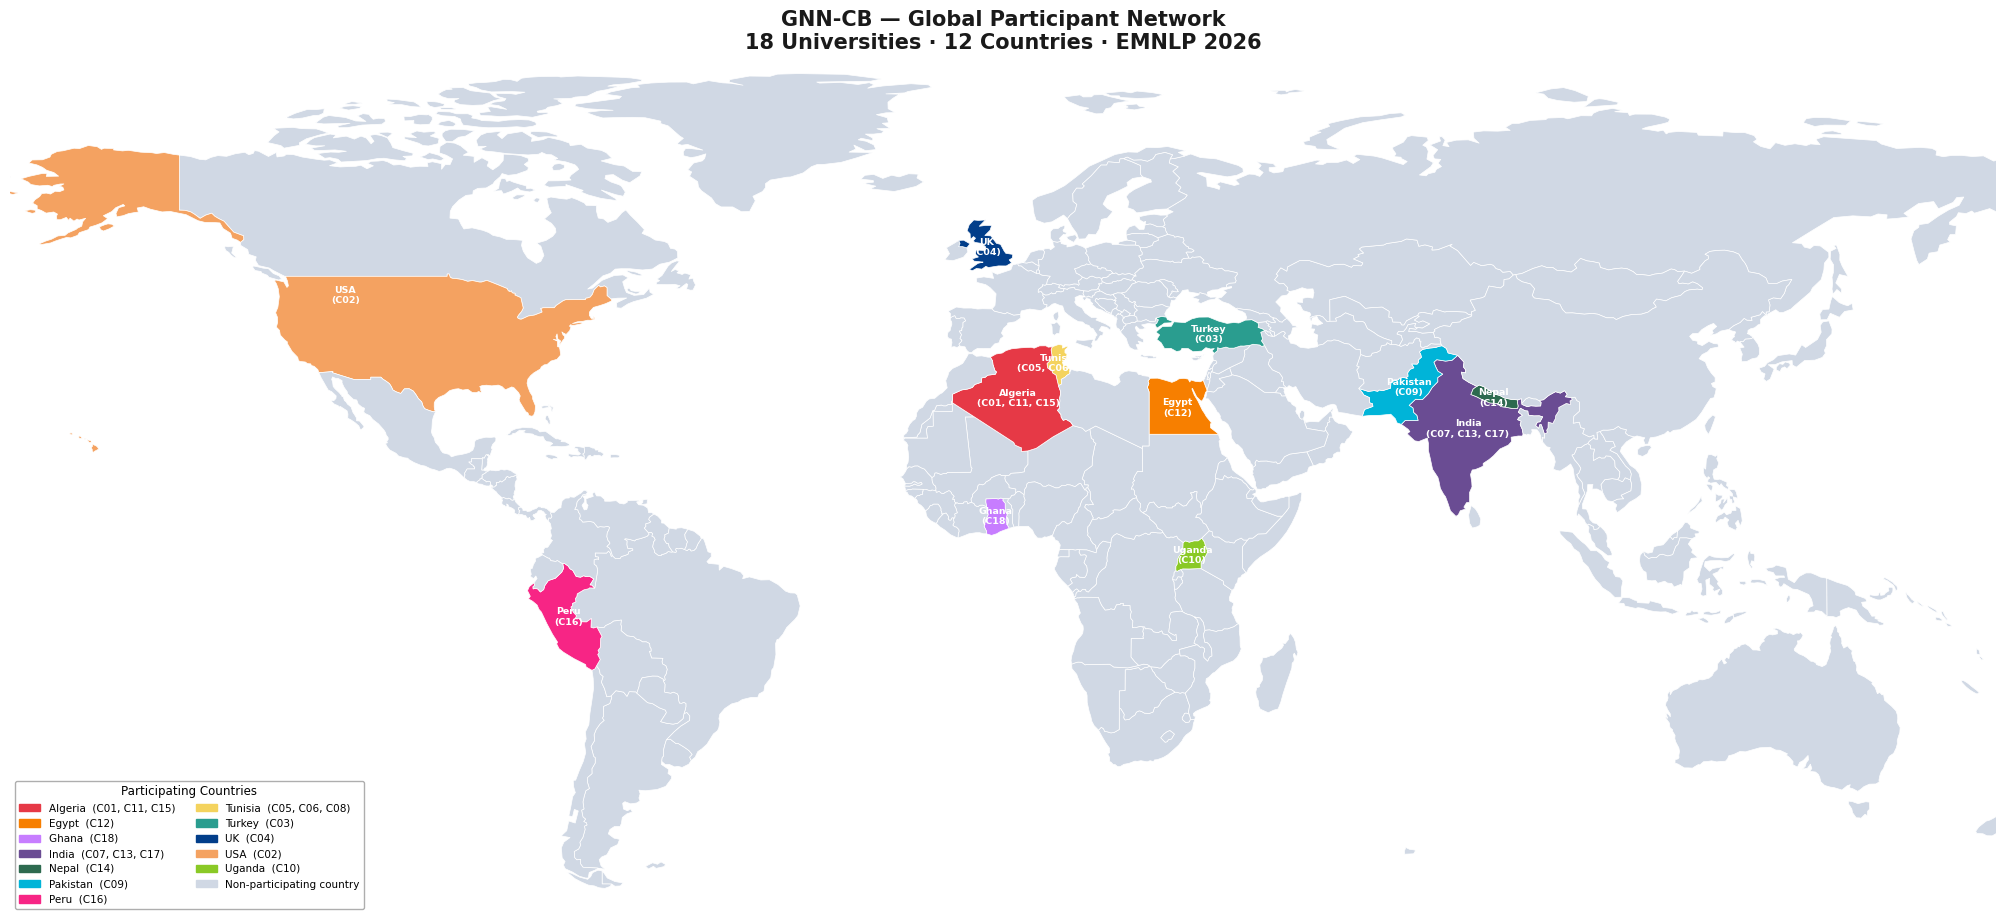
Global Participation
GNN-CB is supported by a globally distributed cohort of contributors
from 18 universities across 12 countries and five continents. The
benchmark was intentionally designed to reflect broad geographic and
institutional diversity spanning Africa, the Americas, Asia, and Europe.
This diversity helps ensure that the curated competitions, datasets,
and evaluation settings are not centered around a single regional
research community, while also providing a heterogeneous human expert
baseline.
Geographic distribution of participating institutions contributing to GNN-CB.
Citation
If you use GNN-CB in your research, please cite:
@inproceedings{gnncb2026,
title = {GNN-CB: A Graph Neural Network Competition Benchmark
for Human and LLM Evaluation},
author = {Anonymous},
booktitle = {Proceedings of the 2026 Conference on Empirical
Methods in Natural Language Processing (EMNLP)},
year = {2026}
}